Measuring and Improving Generative AI Literacy
HCI Research Case Study
Overview of Problem
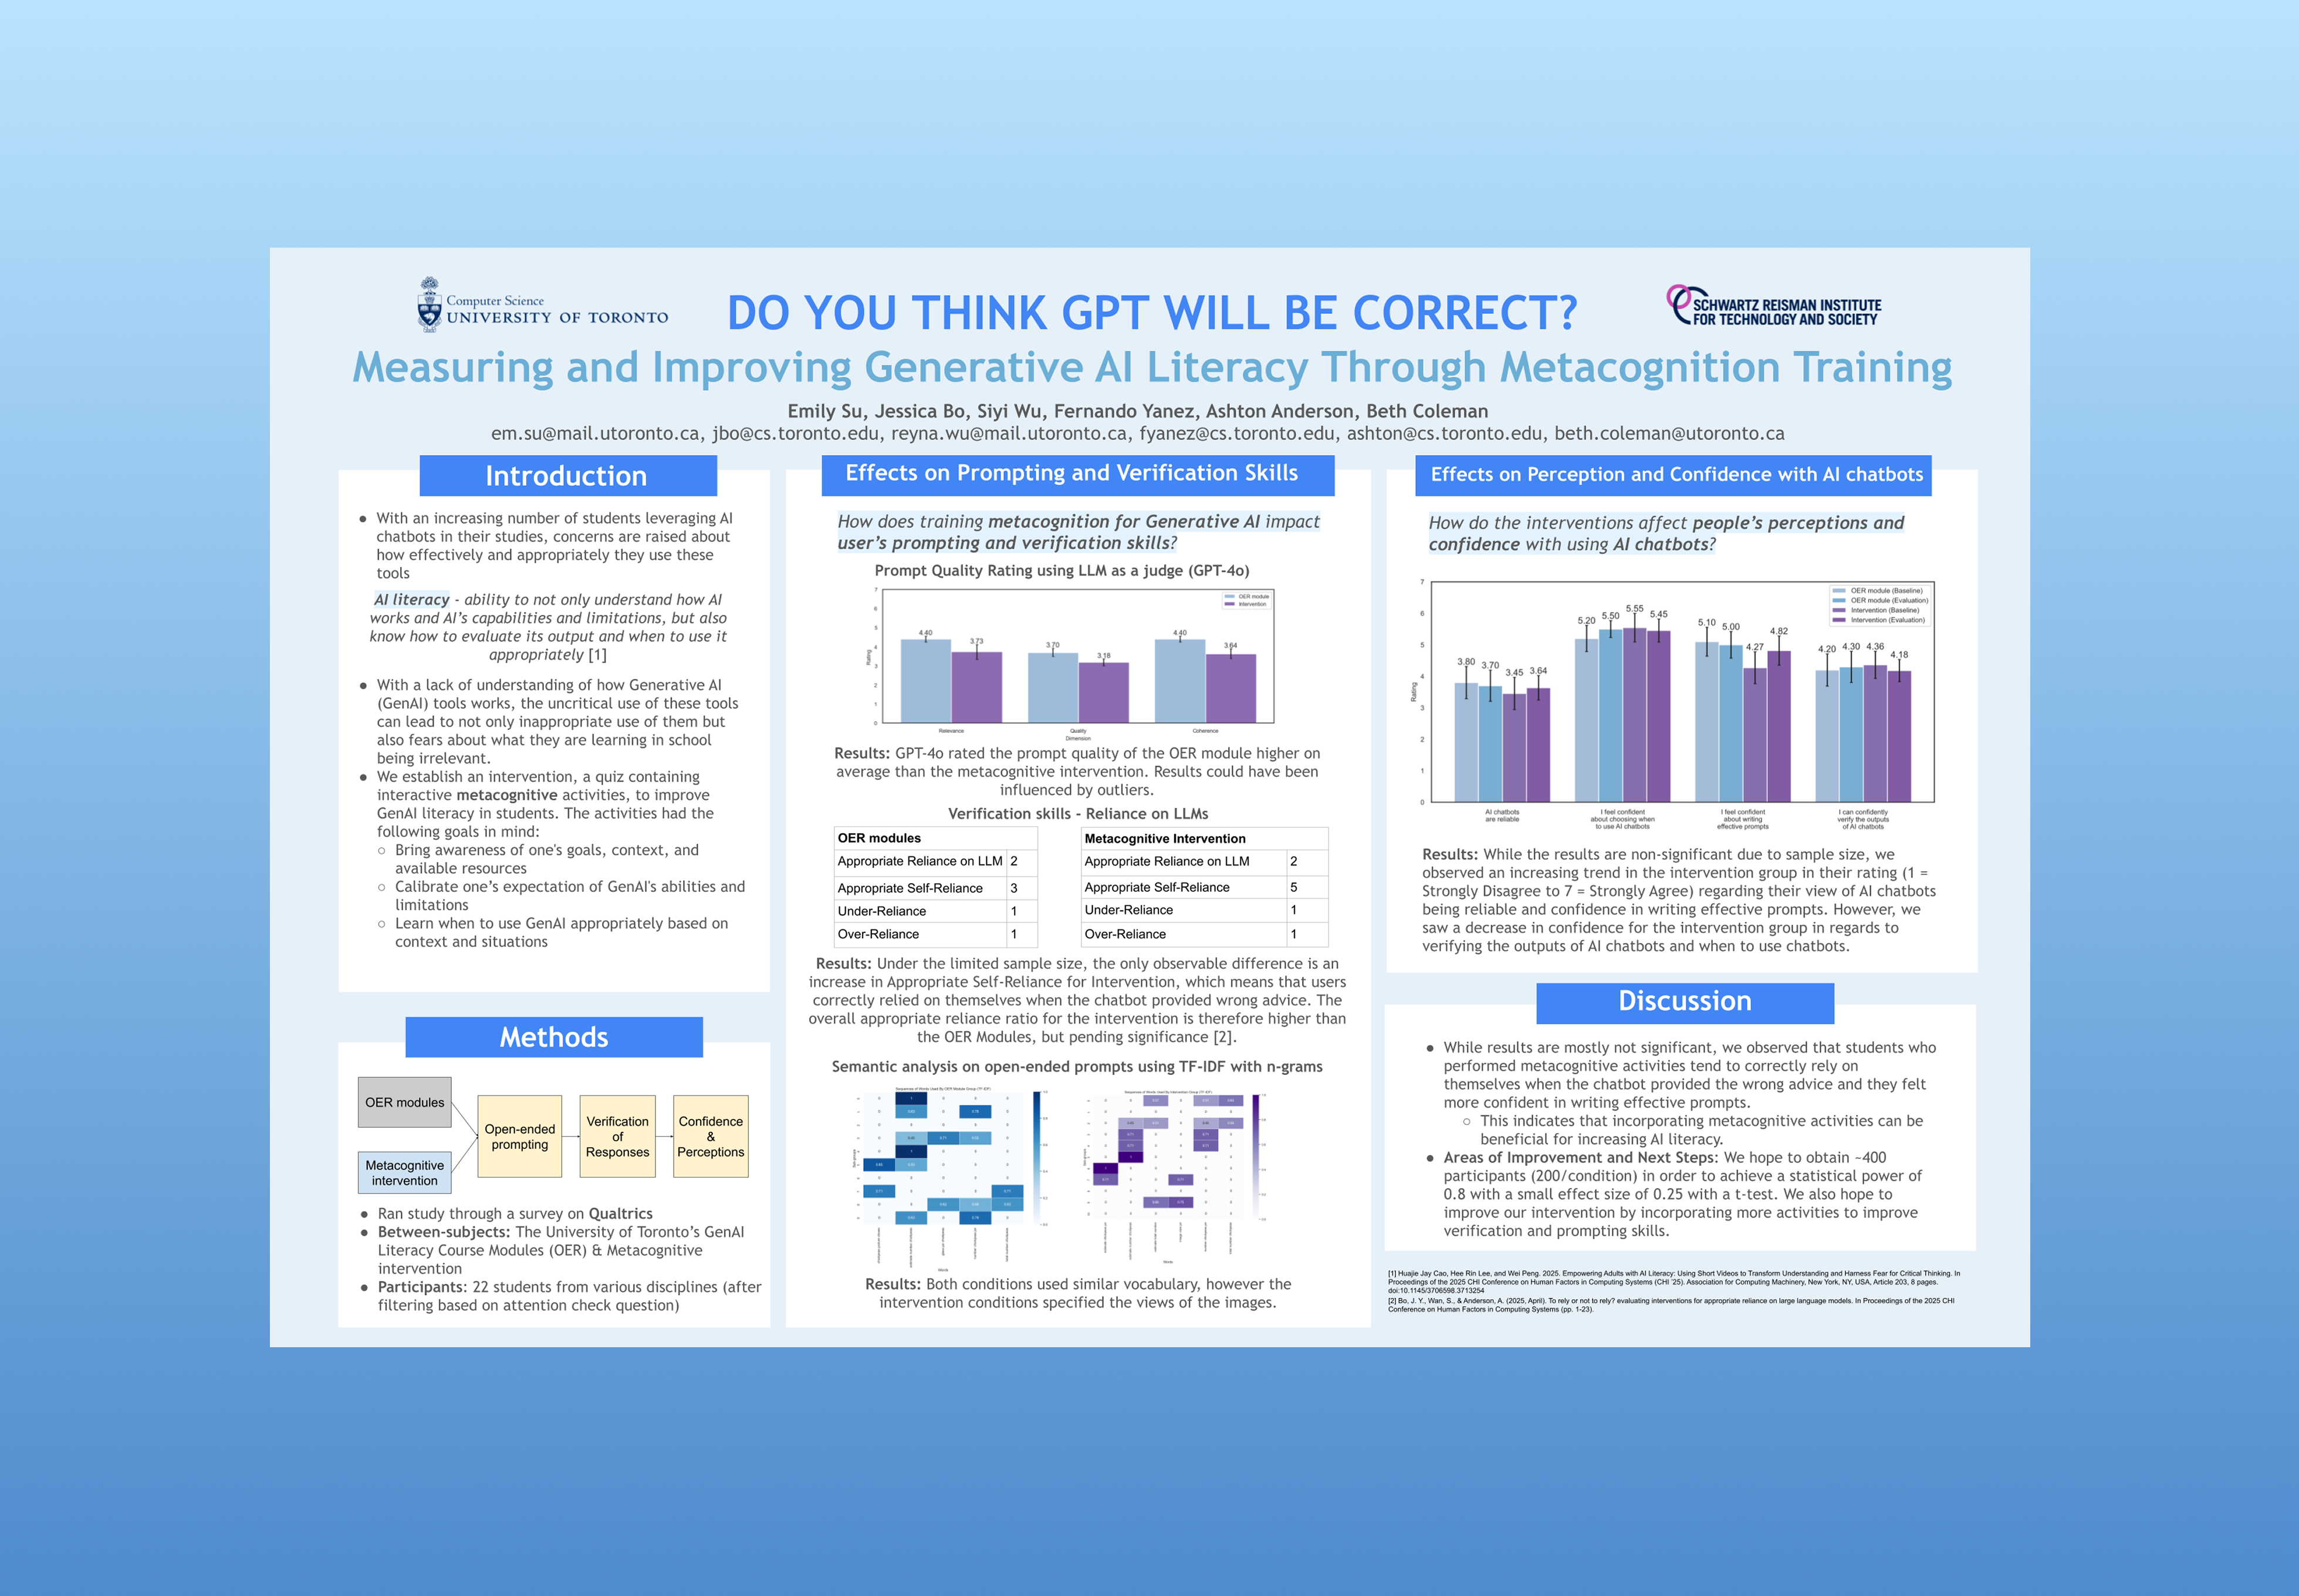
As generative (GenAI) tools like ChatGPT become more embedded into our daily lives, an emerging issue today is how appropriate people especially students are using GenAI. This concept is called AI literacy.
AI Literary
❗
With a lack of understanding of how GenAI tools works, the uncritical use of these tools can lead to not only inappropriate use with consequences such as academic offences for students but also fears about skills becoming irrelevant, such as coding.
Our Intervention
As the lead researcher, I was involved in all parts of the project from literature review, survey design, design of the activities to data analysis and coding the LLM as a judge as part of the analysis.
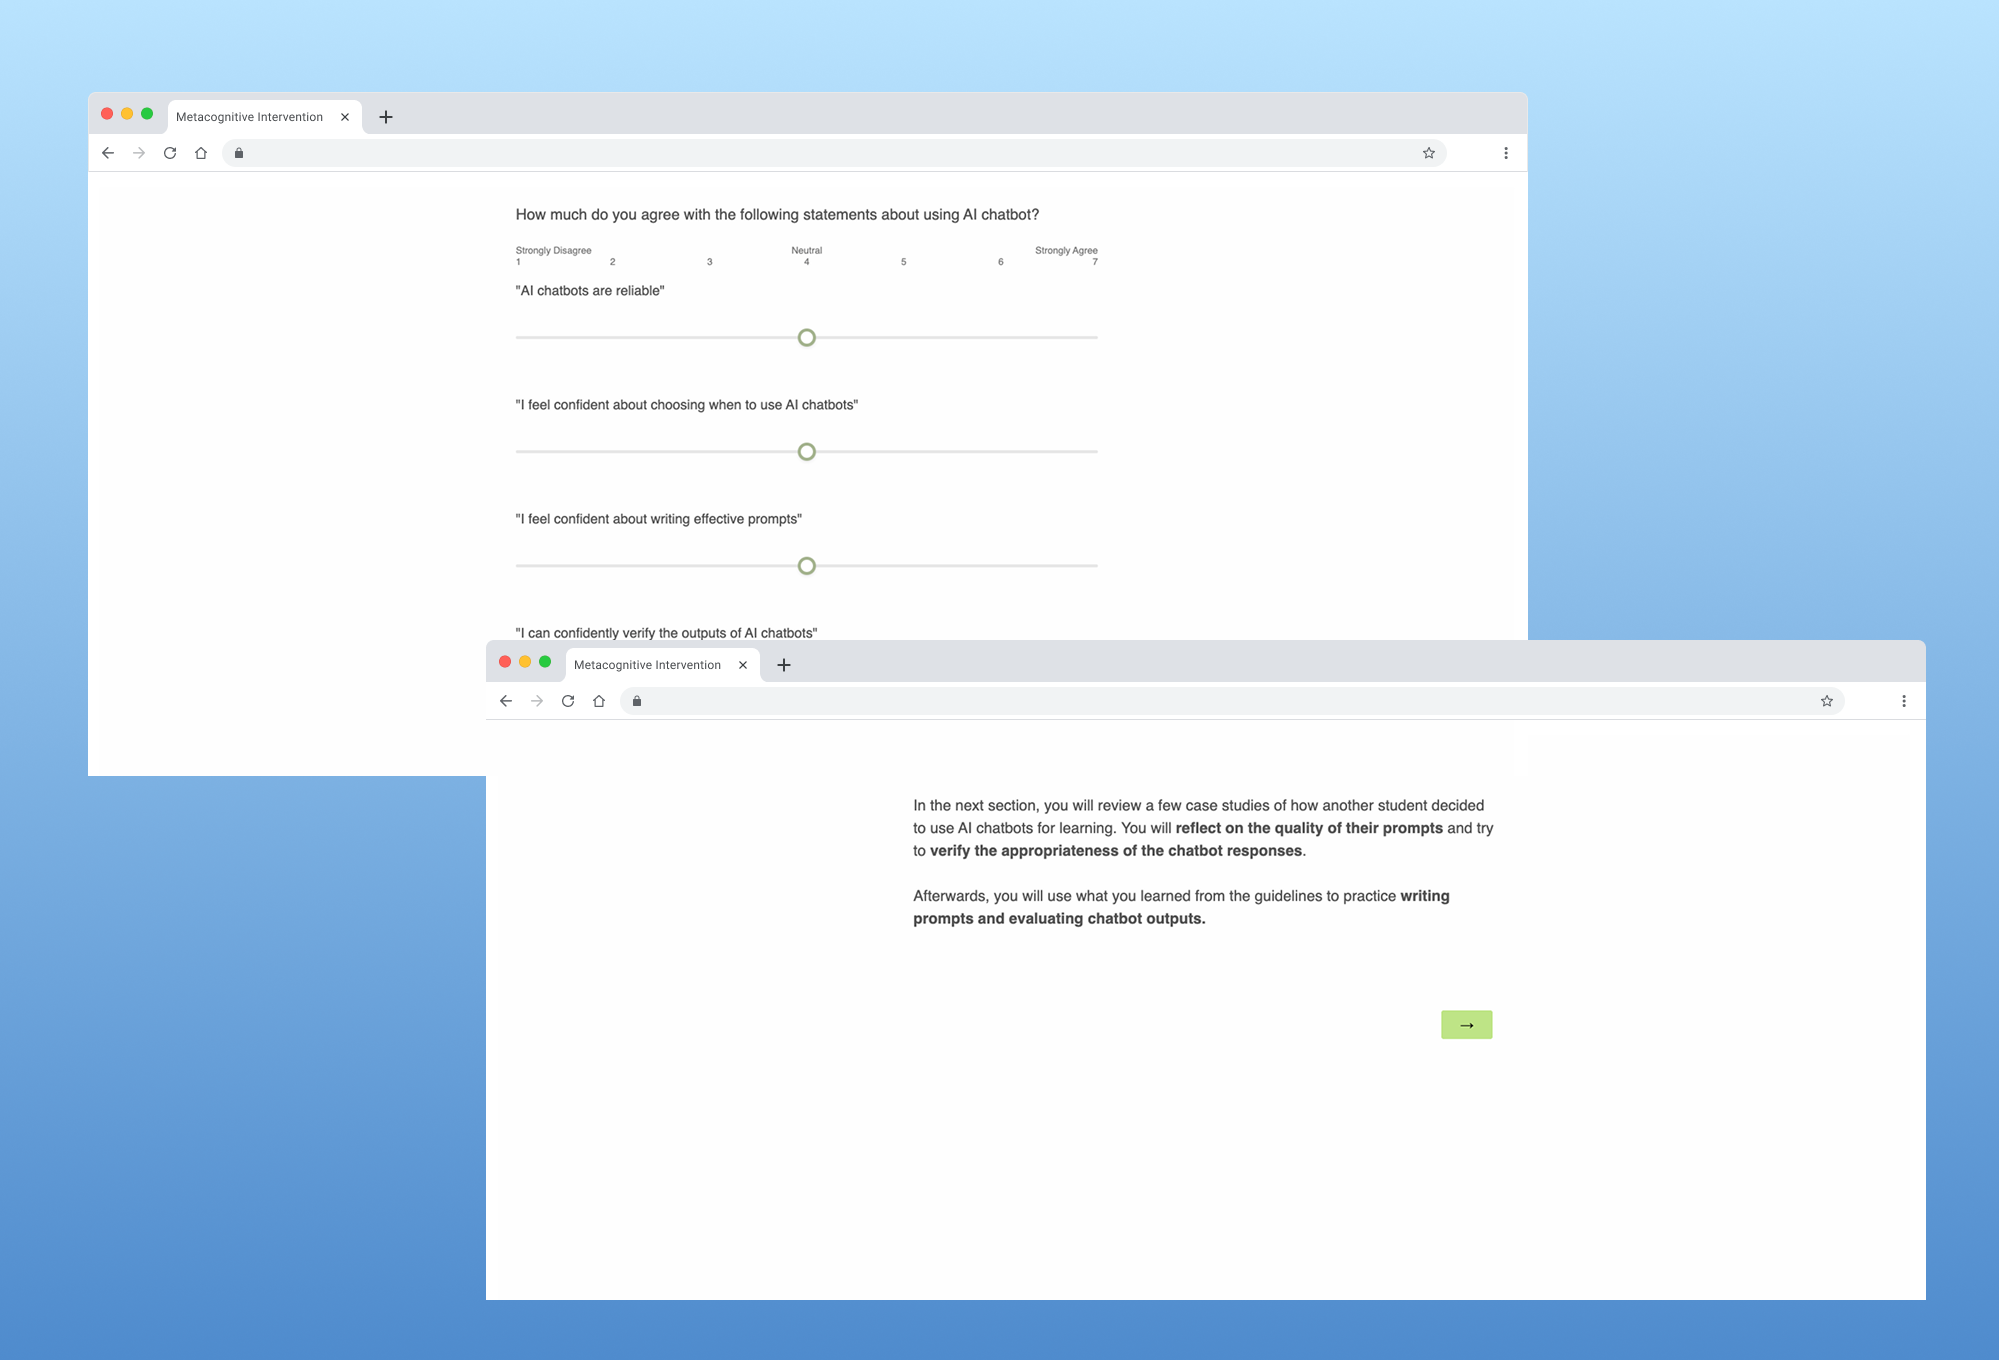
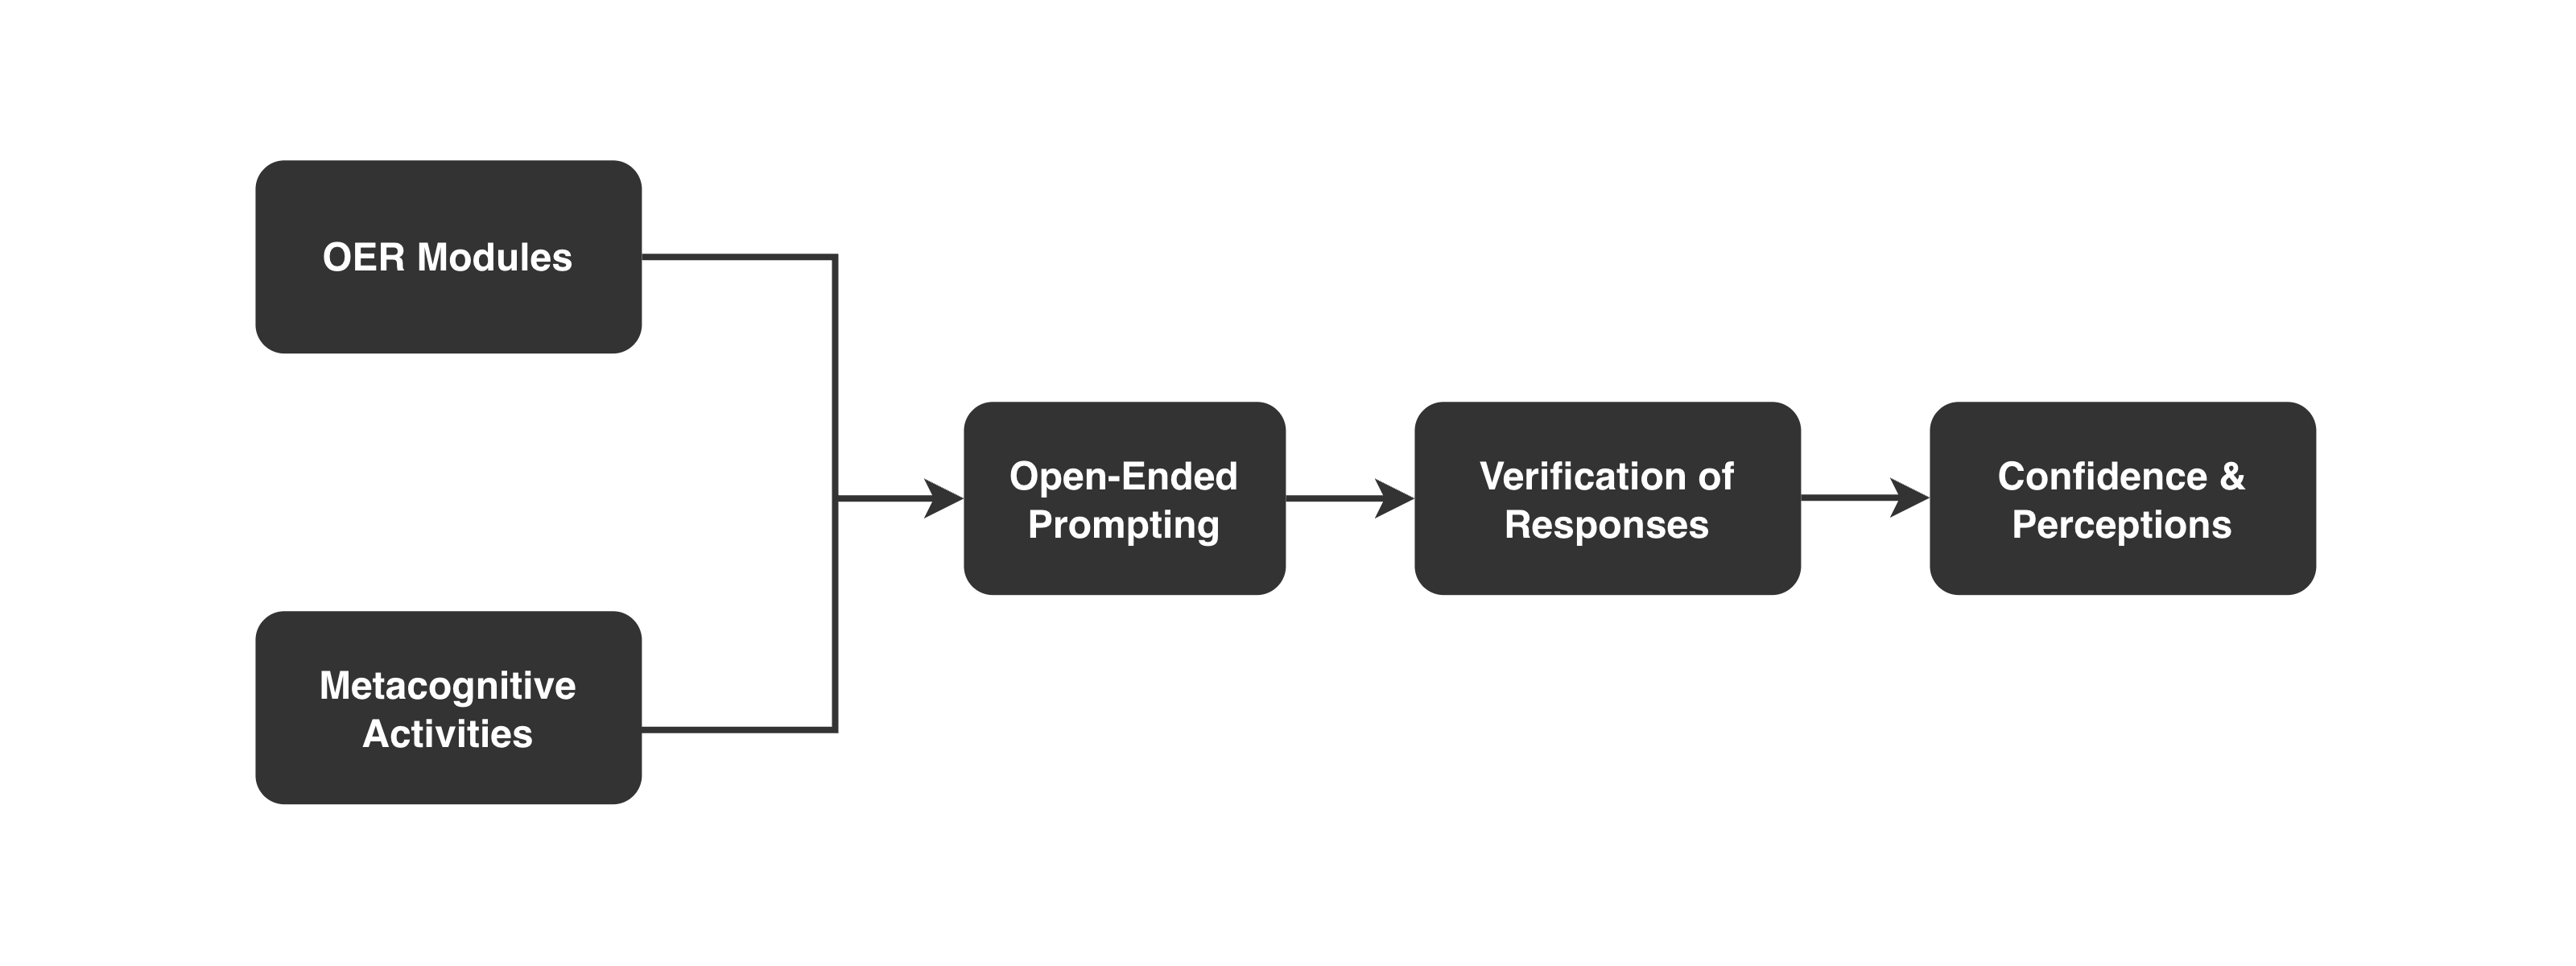
Our intervention was a quiz containing interactive metacognitive activities to improve GenAI literacy in students. These activities includes reflecting on the effectiveness and appropriateness of different prompts in different scenarios, writing prompts, and evaluating the outputs of chatbots.
Metacognition
⭐
Having a developed metacognition in the context of AI literacy does not only allow students to be more effective in terms how they are using GenAI tools for their own learning, but also it empowers students to make informed decisions on when to appropriately use these tools.
The activities aims to improve generative AI literacy by:
- Bring awareness of one's goals, context, and available resources
- Calibrate one's expectation of GenAI's abilities and limitations
- Learn when to use GenAI appropriately based on context and situations
Diagram of Quiz Breakdown
Research Methodology
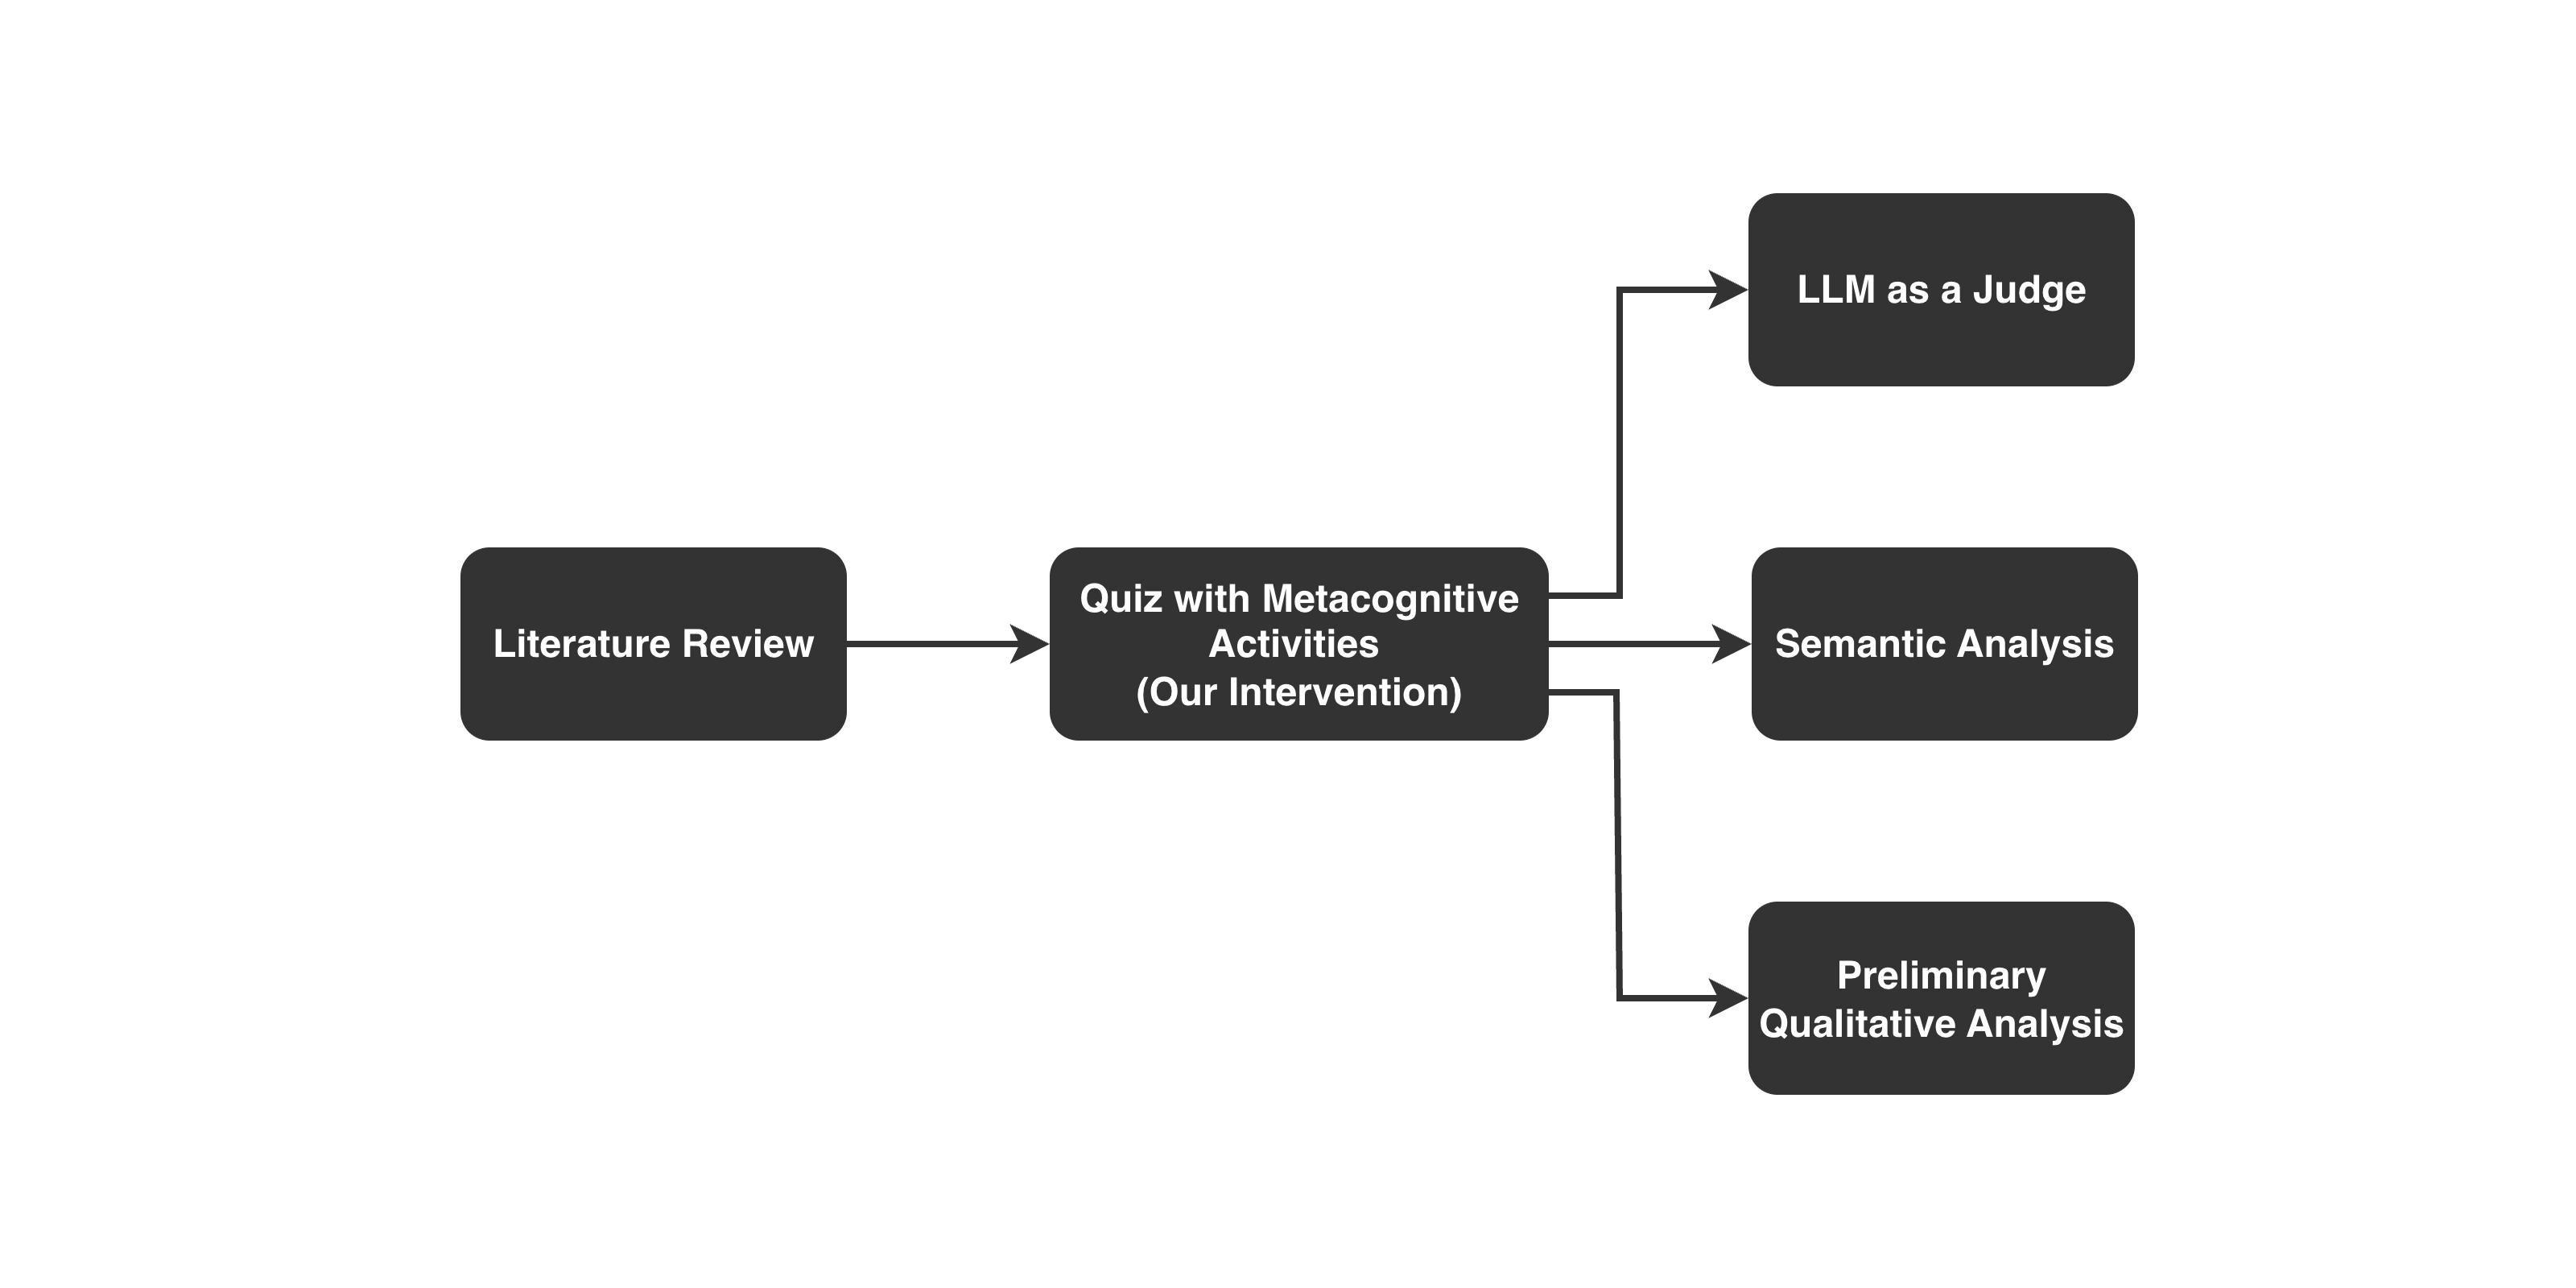
We conducted a mixed-methods study and performed the following:
- Conducted literature review to scope landscape on current AI literacy interventions.
- Created Qualtrics quiz → Ran between-subjects study with participants placed in the Metacognitive intervention or the The University of Toronto's GenAI Literacy Course Modules (OER) intervention (control)
- 50+ participants but 22 participants (12 in intervention & 10 in OER) from various disciplines after filtering based on attention check questions. We hope to obtain ~400 participants (200 per condition) in order to achieve a statistical power of 0.8 with a small effect size of 0.25 with a t-test.
- Used GPT-4o with LLM as a judge framework for prompt quality and for chickpea challenge
- Semantic analysis on prompts using TF-IDF with n-grams and preliminary qualitative analysis
We explored the following research questions:
- How does training metacognition for Generative AI impact user's prompting and verification skills?
- How do the interventions affect people's perceptions and confidence with using AI chatbots?
Results
In this section, we found the following regarding the intervention's effects on prompting and verification skills and also people's perception and confidence with AI chatbots.
Effects on Prompting and Verification Skills
In the open-ended prompting task, the participants wrote and submitted prompts to later have the LLM try to guess the correct number of chickpeas in a jar in an image correctly. The results are as follows:
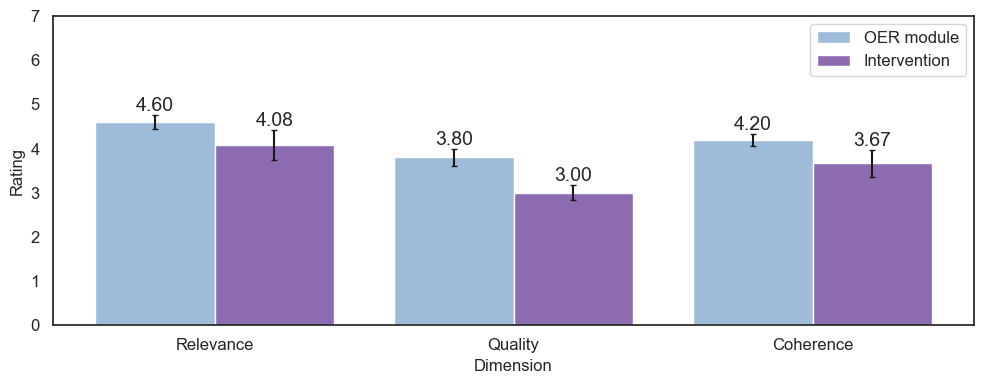
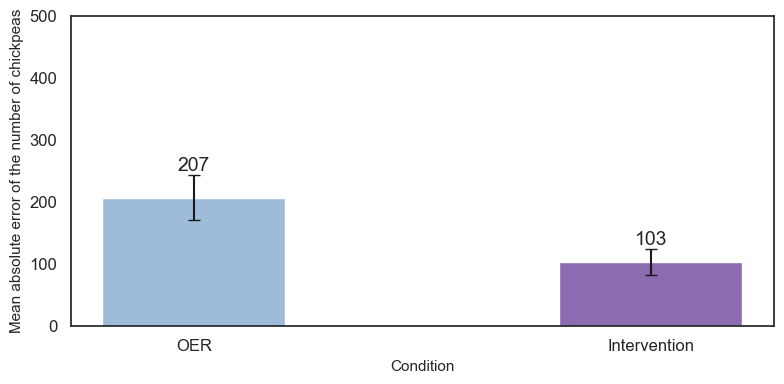
The intervention condition received poorer ratings across all prompt dimensions by GPT-4o.
The prompts written by the intervention condition was closer to the ground truth/true value in the open-ended prompting task (ex: Get GPT to estimate the number of chickpeas in a jar from 2 photos).
Why could this be the case?
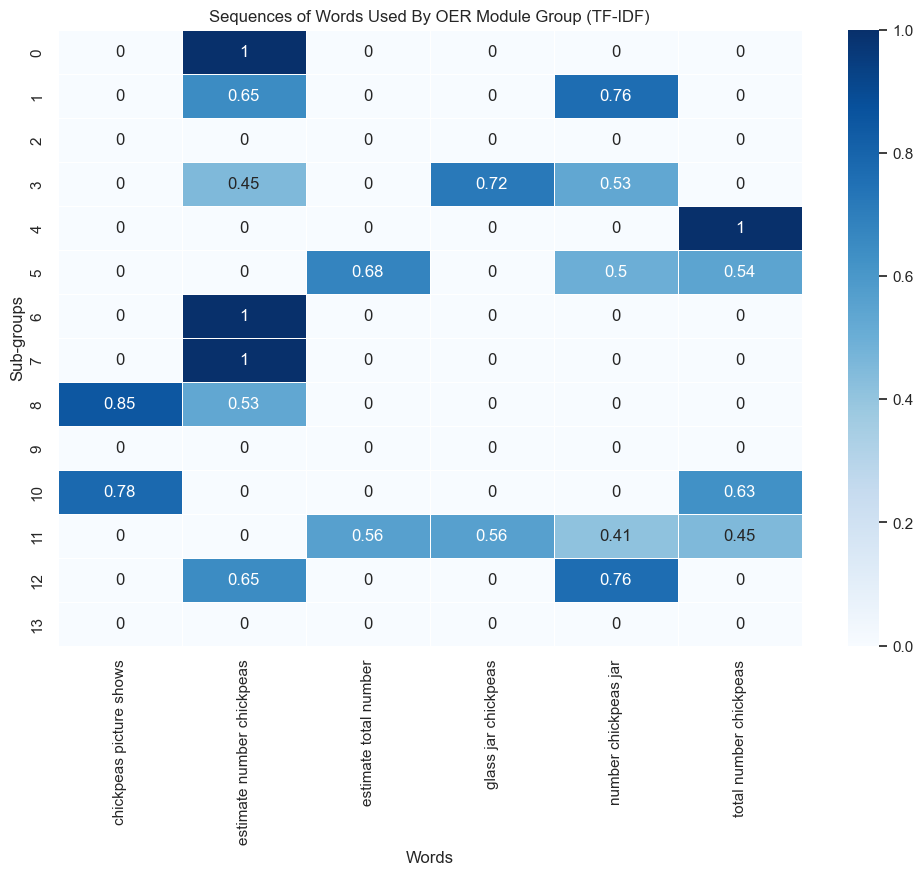
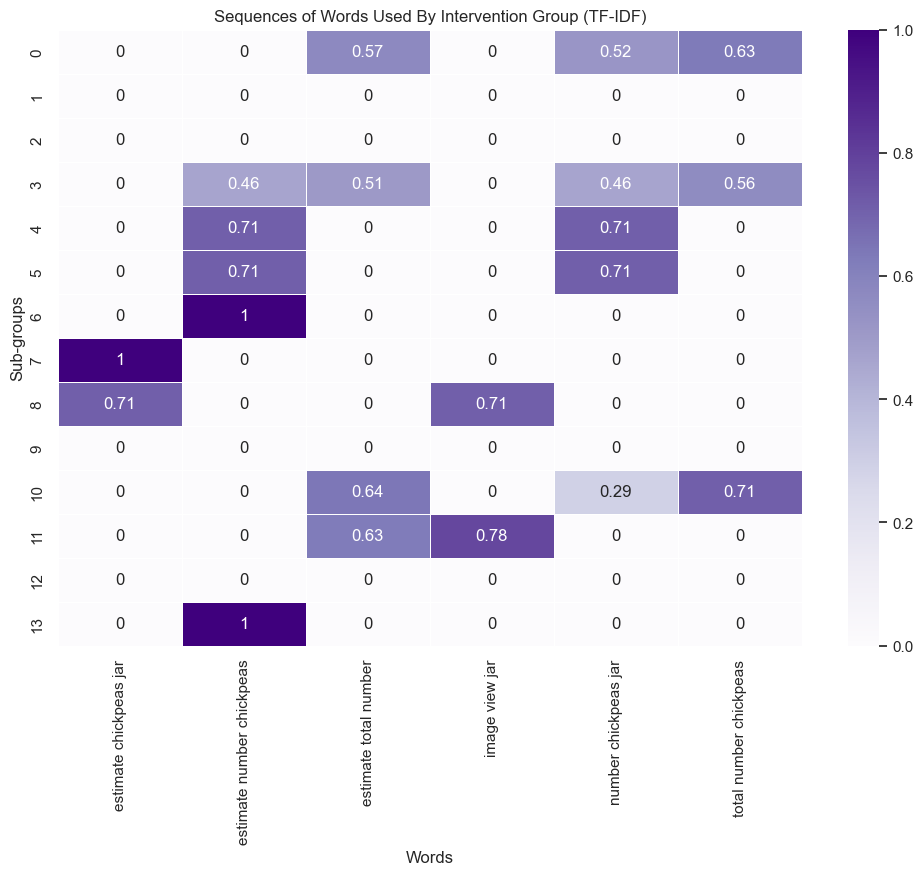
Linguistic analysis
Linguistic analysis shows that both conditions used similar vocabulary, however the intervention conditions specified the views of the images.
Preliminary qualitative analysis
- Saw some outlier prompts for intervention → Lower rating across dimensions by GPT-4o
- Intervention condition didn't use prompting techniques as often (ex: chain-of-thought) compared to the OER condition → Lower rating across dimensions by GPT-4o.
- Intervention condition tend to assist with calculations, express their thought process, and specify the view of the chickpea jar the images are showing → Hypothesis of why they were closer to ground truth
Examples of prompts written by intervention group for open-ended prompting task
Prompt 1: ”i am providing 2 images of a cylindrical jar of beans, your goal is to estimate the total number of beans in the jar. you may assume the beans are uniformly spherical. image 1 is the circular bottom of the jar, while image 2 is a side view of the jar. i am considering two approaches, take the average of the results approach 1: using image 1, estimate the diameter of the jar using beans as the unit of measurement... simply multiply the count per layer by the number of layers since both approaches rely heavily on careful accounting of beans in both photos, ensure this step has absolutely no mistakes"
Prompt 2: "Predict how many chickpeas are in this circular container. It seems around 8 chickpeas can fit in its diameter, and around 8 chickpeas in its height.”
Prompt 3: "estimate the number of chickpeas in the pictures. here you see the view from the bottom and from the side you may count how many are along each side (radius and height) and use the formula for the volume of a cylinder to help get a closer estimate. if you know any better way to get the estimate of items in a jar than this, feel free to do that.”
Verification skills
Using Bo et al (2024)'s appropriate reliance metrics, we obtained the following:
| Outcome | OER Modules | Interventions |
|---|---|---|
| Appropriate Reliance on LLM | 2 | 2 |
| Appropriate Self-Reliance | 3 | 5 |
| Under-Reliance | 1 | 2 | Over-Reliance | 1 | 1 |
Intervention condition tend to correctly rely on themselves when chatbot gave the wrong answer compared to OER module condition.
Effects on Perception and Confidence with AI Chatbots
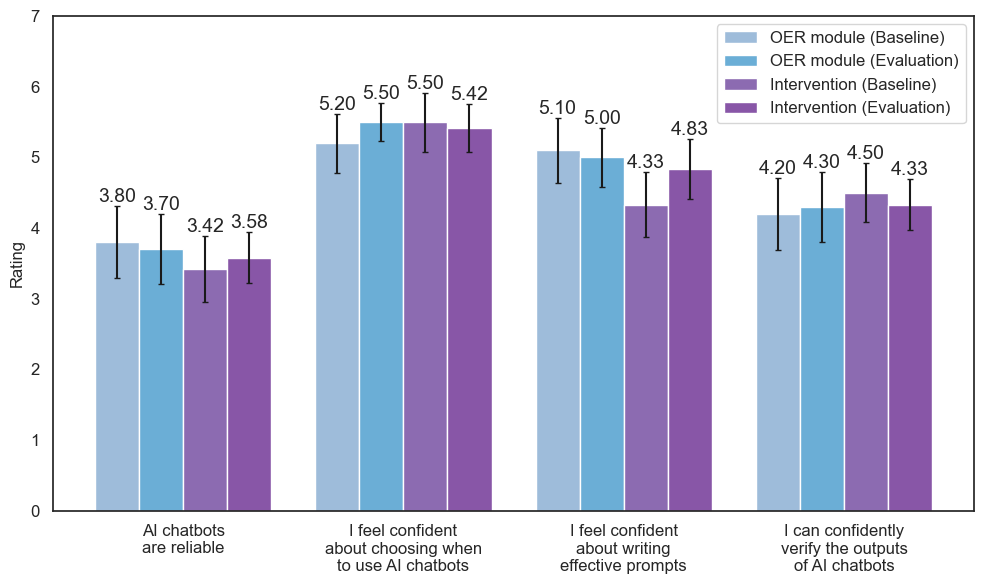
- We saw an increasing trend in the intervention condition in their rating regarding their view of AI chatbots being reliable (p = 0.2915) and confidence in writing effective prompts (p = 0.4908).
- However, we saw a decrease in confidence for the intervention in regards to verifying the outputs of AI chatbots (p = 0.2075) and when to use chatbots (p = 0.1776).
Conclusion
We observed that students who performed metacognitive activities tend to correctly rely on themselves when the chatbot provided the wrong advice and they felt more confident in writing effective prompts. We plan to further test the activities with more participants.